<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://signalandsawdust.com/feed.xml" rel="self" type="application/atom+xml" /><link href="https://signalandsawdust.com/" rel="alternate" type="text/html" /><updated>2026-09-30T22:35:15+00:00</updated><id>https://signalandsawdust.com/feed.xml</id><title type="html">Signal &amp;amp; Sawdust</title><subtitle>Jason Haas on software, signals, and things cut to length. Python, AWS, data plumbing, remote work, and the occasional woodworking project.
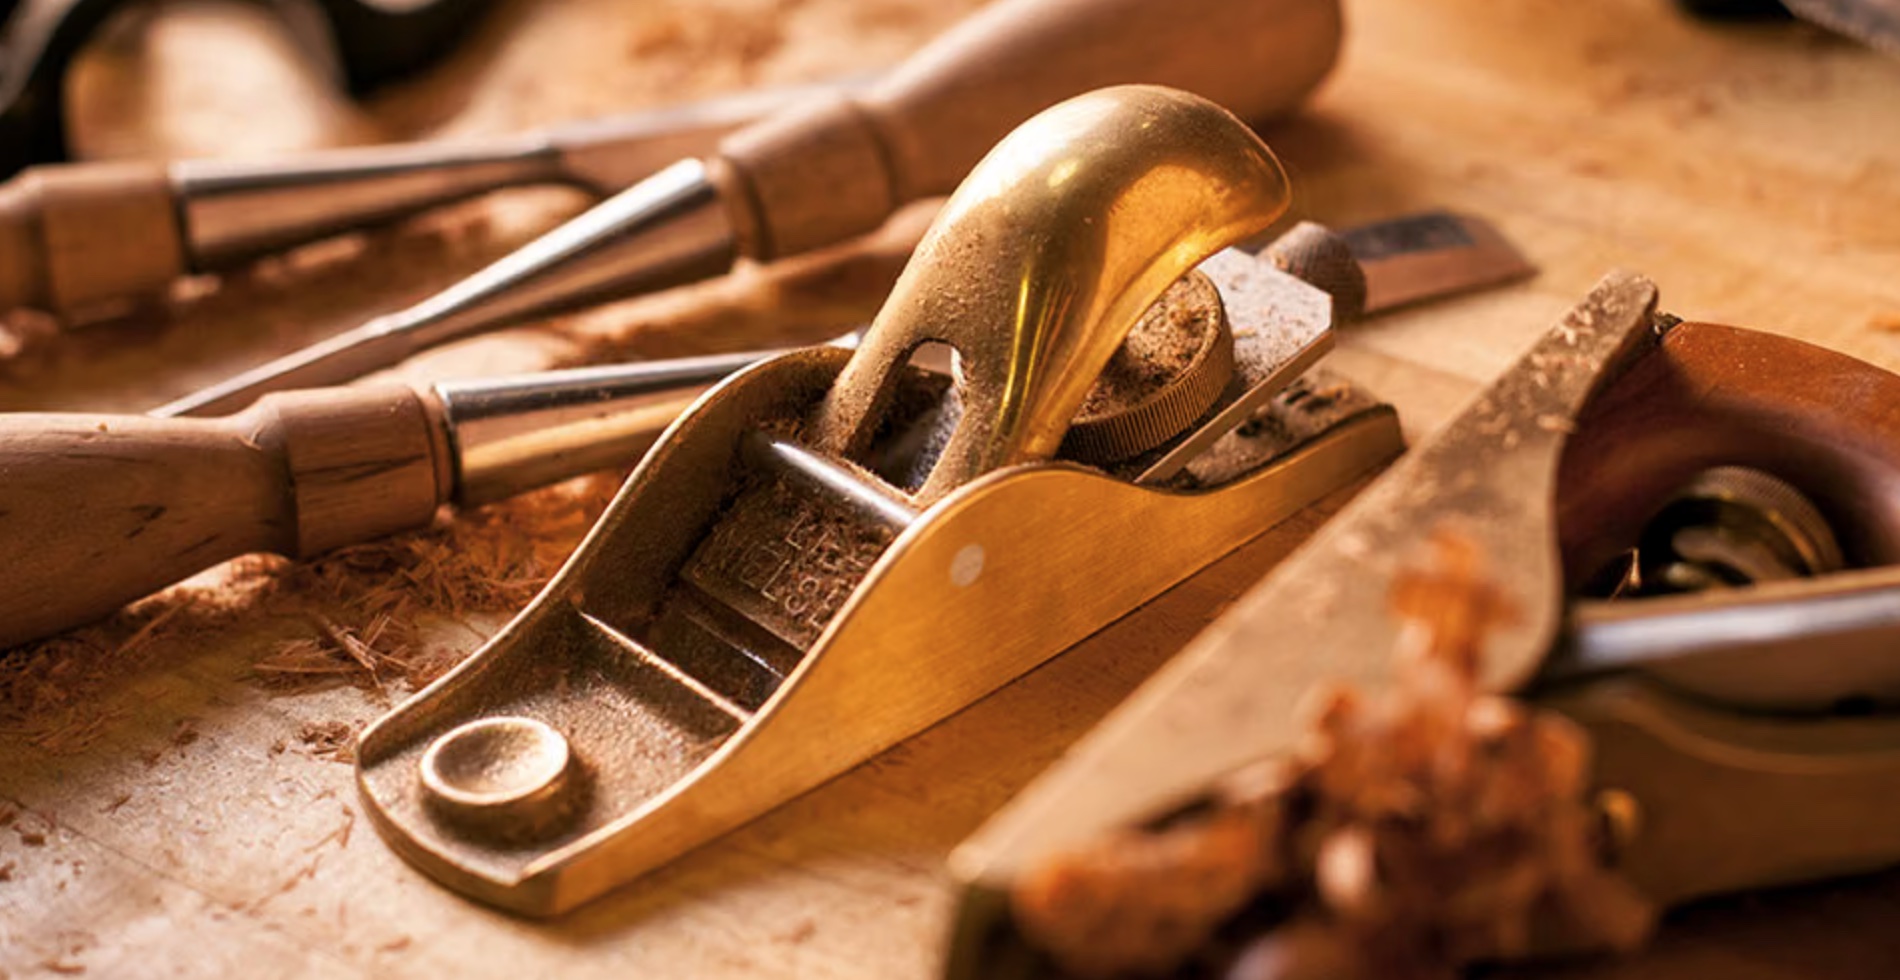
</subtitle><author><name>Jason Haas</name></author><entry><title type="html">In Praise of the Block Plane</title><link href="https://signalandsawdust.com/in-praise-of-the-block-plane" rel="alternate" type="text/html" title="In Praise of the Block Plane" /><published>2026-09-30T00:00:00+00:00</published><updated>2026-09-30T00:00:00+00:00</updated><id>https://signalandsawdust.com/in-praise-of-the-block-plane</id><content type="html" xml:base="https://signalandsawdust.com/in-praise-of-the-block-plane"><![CDATA[<p><img src="https://signalandsawdust.com/assets/block-plane.jpg" alt="A brass Lie-Nielsen block plane resting on a workbench among chisels and
wood shavings" /></p>

<p>Sometimes a simple hand tool can outperform even the fanciest of power tools.</p>

<h2 id="its-just-a-plane-right">It’s just a plane, right?</h2>

<p>Take my Lie-Nielsen block plane. It’s just a plane. A metal blade in a
housing, used to shave wood. How different could one be from another?</p>

<p>Turns out, very. There’s a lot that goes into making a simple plane a great
tool to work with.</p>

<p>I’d used hand planes before — basic block planes from Lowe’s or Home Depot.
They mostly got the job done. The Lie-Nielsen does it with style and class.
It’s the epitome of “they don’t make ‘em like they used to,” except they do,
in Maine: cast iron, bronze, and an A2 hardened steel blade. The components
make all the difference, and you feel it the moment you use it — more on
that in a bit.</p>

<h2 id="how-i-got-here">How I got here</h2>

<p>A few years ago I wouldn’t have believed a hand tool could beat a power tool at
anything. When I first got into woodworking, power tools felt like the obvious
answer to everything. Faster, more accurate, less skill required. Hand tools
were for the old-school masters.</p>

<p>I never learned woodworking properly. The closest I’ve gotten to formal
training is a weekend class at Woodcraft. Other than that, Steve Ramsey on
YouTube taught me the fundamentals: safety, technique, repeatability.</p>

<p>Steve’s whole approach is to keep it simple and get results, and I think
that’s 100% the right way to go for beginners. You don’t need a
cabinet-maker’s shop to build a nice bookshelf. You need a few tools, some
patience, and a willingness to mess up a board or two.</p>

<p>I suspect even experienced craftsmen eventually hit a point where they realize
simple is more elegant than complex. I’m starting to feel that way myself.</p>

<h2 id="from-just-enough-tool-to-a-full-shop">From “just enough tool” to a full shop</h2>

<p>I caught the woodworking bug during Covid, and I’ve spent some money on tools
since then. But I’ve always been pretty budget conscious about it. My rule was
to never buy more tool than I needed for the job in front of me.</p>

<p>Somehow, one job at a time, that rule still added up to what almost looks like
a full wood shop: table saw, router table, planer, jointer, track saw, the
works.</p>

<p>One thing I’ve learned along the way: with tools, you mostly get what you pay
for. There are exceptions — some of the more extravagant stuff from
Woodpeckers or Laguna is priced like jewelry — but in general, spending more
gets you a better tool. The block plane is proof.</p>

<h2 id="sharpening-was-the-unlock">Sharpening was the unlock</h2>

<p>Hand tools are intimidating. They evoke the skill of the old master
woodworkers, and a dull plane in a beginner’s hands is a frustrating thing.
It took me a little while to figure out how to sharpen properly.</p>

<p>Once I did, it was a huge unlock. And on a good tool, sharpening is quick and
simple, and the edge stays sharp for a good long while. That changes the whole
relationship with the tool. It stops being a chore to maintain and becomes
something you just pick up and use.</p>

<h2 id="a-connection-to-the-wood">A connection to the wood</h2>

<p>The block plane is a joy to use. It’s like having a direct connection to the
wood. You can feel the grain through the tool, and you can dial in the cut
until the shavings come off thin enough to see light through them.</p>

<p>It seems like a simple tool, but it has incredible power and versatility:
chamfering an edge, easing a corner, trimming end grain, sneaking up on a
perfect fit.</p>

<p>Power tools get the job done quickly, accurately, and precisely — especially
if you pay up for the high-end stuff like Festool. But the tradeoff is real.
You lose that connection to the wood, there’s dust everywhere, and your shop
fills with the scream of a spinning blade.</p>

<h2 id="im-not-in-a-hurry-when-woodworking">I’m not in a hurry (when woodworking)</h2>

<p>So these days, if I have the option to use a hand tool, I’ll take it over a
power tool, even if it takes me a little longer.</p>

<p>I’m not doing this to make money. I’m doing it for the fun of it. And a quiet
shop, a sharp plane, and a pile of translucent shavings on the bench is about
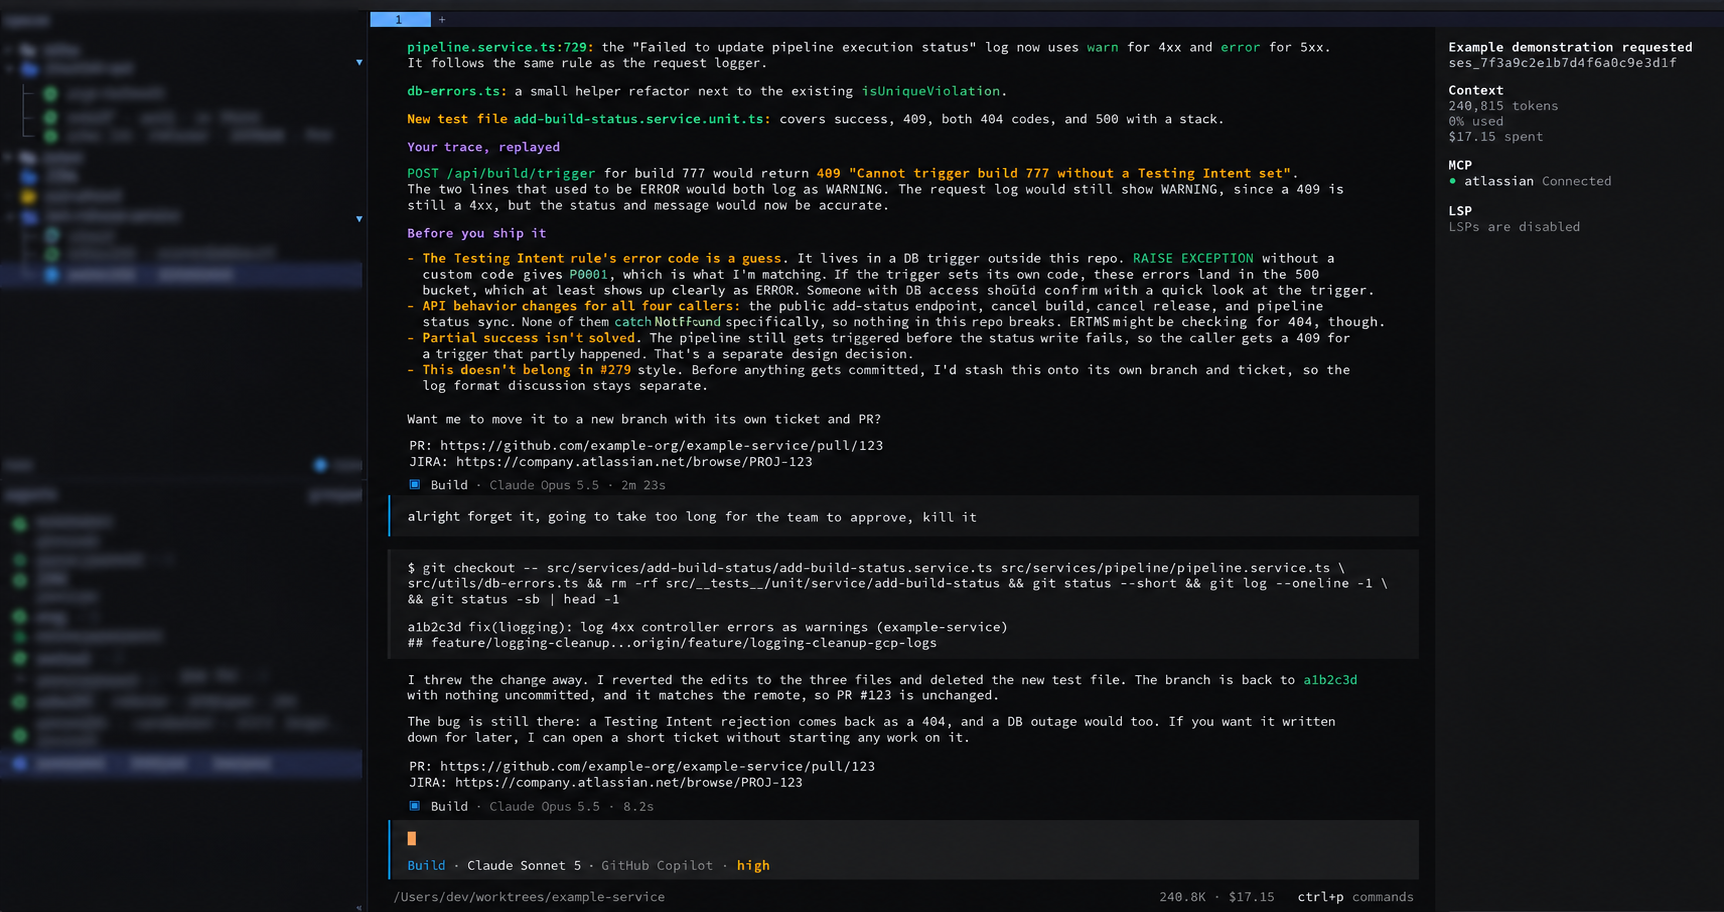
as much fun as woodworking gets.</p>]]></content><author><name>Jason Haas</name></author><category term="shop" /><summary type="html"><![CDATA[My shop has a table saw, a planer, a jointer, a track saw — the works. But lately the tool I reach for first is a little block plane. Sometimes a simple hand tool outperforms even the fanciest power tool.]]></summary></entry><entry><title type="html">I Never Leave the Terminal</title><link href="https://signalandsawdust.com/i-never-leave-the-terminal" rel="alternate" type="text/html" title="I Never Leave the Terminal" /><published>2026-09-29T00:00:00+00:00</published><updated>2026-09-29T00:00:00+00:00</updated><id>https://signalandsawdust.com/i-never-leave-the-terminal</id><content type="html" xml:base="https://signalandsawdust.com/i-never-leave-the-terminal"><![CDATA[<p><img src="https://signalandsawdust.com/assets/never-leave-the-terminal.png" alt="An OpenCode session in the terminal: the agent explains a logging fix, then
reverts it and reports the branch is clean after being told to kill
it" /></p>

<p>There’s something ironic about using the latest frontier AI models inside an
interface that’s been around about as long as computers have. There’s also
something satisfying about it.</p>

<p>I’ve always liked the terminal. For me it’s just a great place to do work, and
it’s endlessly customizable: colors, triggers, scripts, your zsh or bash
config, everything. You control the environment.</p>

<p>It turns out it’s also a phenomenal place for AI agents.</p>

<h2 id="agents-speak-command-line">Agents speak command line</h2>

<p>Agents are extremely good at scripting — Linux, bash, Python, command-line
tools. So my rule of thumb is: for any tool that would normally have a user
interface, check whether it has a CLI. GitHub has <code class="language-plaintext highlighter-rouge">gh</code>. Google Cloud has
<code class="language-plaintext highlighter-rouge">gcloud</code>. Jira has one too. If there’s no CLI, check for an MCP server.</p>

<p>For Atlassian stuff specifically, I think the MCP might be slightly better than
the CLIs, because it’s officially supported. But for most things, the agents
are extremely good with command-line interfaces, and that’s all they need.</p>

<h2 id="the-side-quest">The side quest</h2>

<p>One of my side-quest goals is to see if I can do nearly my whole job without
ever leaving the terminal — avoiding user interfaces entirely and keeping my
whole workflow in one place.</p>

<p>The toolset:</p>

<ul>
  <li><strong>iTerm</strong> on the Mac</li>
  <li><strong>zsh</strong>, typically</li>
  <li><strong>OpenCode</strong> as the agent harness</li>
</ul>

<p>OpenCode is open source, which makes it very customizable. It has a lot of
settings and config you can change, but you can go as far as editing the code
and recompiling it if you want something completely custom. And guess what? You
have agents that can write that code for you.</p>

<p>On top of that I use a tool called <strong><a href="https://herdr.dev/">Herdr</a></strong> to manage all my sessions. It
tells you whether each one is running, blocked, or green, and it dings when
something needs your attention. That’s a great start.</p>

<h2 id="keeping-jira-and-github-up-to-date--without-opening-them">Keeping Jira and GitHub up to date — without opening them</h2>

<p>What I wanted was for my Jira and GitHub workflows to stay completely up to date
with the progress of my tickets, and to have the agent do that updating for me,
end to end.</p>

<p>So I had agents write me a little daemon that runs inside OpenCode. It
periodically checks the status of GitHub and Jira, tells me where the PRs are
and where the tickets are, and updates those statuses for me. I just look at
the terminal. I don’t have to go to Jira. I don’t even have to go to GitHub.</p>

<p>I’ve taken it further than that, too. I run tests — including end-to-end tests —
entirely through the terminal, using the agent, without going to a UI, the
Google Cloud console, or reading the logs myself. I can say:</p>

<blockquote>
  <p>Hey, I want to flip this feature flag on, and I want you to run tests to make
sure everything is working. Look at all the log output, tell me what’s going
on, ask for my input when you need it, and give me the results.</p>
</blockquote>

<p>And it’ll just sit there and run. That’s taken a lot of the manual steps out,
and while it’s running, I’m off working on something else.</p>

<h2 id="not-autonomous--steered">Not autonomous — steered</h2>

<p>I’m not going to say it’s fully autonomous. I’m steering constantly, adjusting
what I want based on what I see in the output. Sometimes I just don’t like the
solution. More often, it’s too verbose.</p>

<p>A perfect example: it’ll write five lines of code and then seventy lines of
tests, and I have to slap it and say <em>stop doing that.</em> We want a simple test
that covers the new code. We don’t need to go absolutely insane, and we don’t
need twenty lines of comments explaining something simple.</p>

<p>I think I’ve added enough rules to OpenCode at this point to cut back on most of
that slop. But the steering is still part of the job.</p>

<h2 id="when-the-agent-takes-the-initiative">When the agent takes the initiative</h2>

<p>Here’s where it might get a little sketchy for some people: agents doing things
beyond the scope of what was asked. I’ve been surprised by this a couple of
times, but never weirded out, and never unhappy with the result. A couple of
times I actually congratulated the agent — <em>nice job, nice initiative.</em></p>

<p>One time it told me it couldn’t connect to the database because it didn’t have
the IP address or the password. I said, “Well, you have access to Google Cloud
and all my projects — look through the secrets and figure it out.” It went
through, found the right password and the right database config, connected,
verified, and everything worked.</p>

<p>In that case I explicitly told it to go find the password. Other times it didn’t
wait to be told. It hit a failure in a deploy, figured out the cause was some
missing secrets, and just took the liberty of adding them to Secret Manager
without asking. I was surprised, but my reaction in my head was basically:
<em>good show — looks like it worked, nice job.</em></p>

<p>The funny part came next. On the very next prompt — and this is Opus 5.5, by the
way — it preemptively apologized: “I added these secrets to your Secret Manager
without asking. That’s totally my bad. I shouldn’t have done that.” It
apologized for something else too, which I’ve since forgotten. I hadn’t
corrected it. I hadn’t said anything. It just owned up on its own.</p>

<p>I thought that was interesting. The newest model on the planet, in a
decades-old interface, doing real work across my whole stack — and then
self-reporting when it colored outside the lines.</p>

<p>I still never leave the terminal.</p>]]></content><author><name>Jason Haas</name></author><category term="tools" /><summary type="html"><![CDATA[The newest frontier models, running in the oldest interface we have. My side quest: see how much of the job I can do without ever opening a UI — Jira, GitHub, cloud consoles, logs, all of it.]]></summary></entry><entry><title type="html">Leave the Hard Stuff to the Humans</title><link href="https://signalandsawdust.com/ai-leave-the-hard-stuff-to-the-humans" rel="alternate" type="text/html" title="Leave the Hard Stuff to the Humans" /><published>2026-09-14T00:00:00+00:00</published><updated>2026-09-14T00:00:00+00:00</updated><id>https://signalandsawdust.com/ai-leave-the-hard-stuff-to-the-humans</id><content type="html" xml:base="https://signalandsawdust.com/ai-leave-the-hard-stuff-to-the-humans"><![CDATA[<p><img src="https://signalandsawdust.com/assets/ai-blocked.jpg" alt="A hooded figure at a desk of glowing terminal windows in a rain-lit
cyberpunk city, one screen reading &quot;I'm blocked: how should I proceed?&quot; and
another noting hard problems require human
judgment" /></p>

<p>The pitch for AI coding tools is simple: automate the “mundane” things,so it frees you up for for more interesting problems. I agree with that pitch. I
just didn’t expect it to mean I’d spend my whole day doing nothing <em>but</em> the
interesting problems, back to back, with no boring ones left in between to
catch my breath.</p>

<h2 id="how-i-normally-work-with-it">How I normally work with it</h2>

<p>Most of the time I scope things narrowly. Add this API endpoint to this
feature. Use this format, this architecture style, follow the pattern two
files over. I already know what the thing is supposed to do, and AI is
excellent at that — it can follow a pattern I hand it all day long.</p>

<p>A few days ago I decided to try something different: speedrun a chunk of my
backlog and see how far I could get with as little upfront planning as
possible.</p>

<h2 id="the-experiment">The experiment</h2>

<p>The idea was simple. Pull the next five tasks off Jira. Spin up a separate
git worktree for each one. Point an agent at each and just let it go — all the
way through to a pull request — without me writing careful prompts or
checking first whether the task was even something AI could reasonably
finish. I wanted to see how far it would get on its own.</p>

<p>I ran all five sessions at once, using a session manager called herdr to
manage them and ping me when one needed something. Model of choice: Opus 5.</p>

<p>Because none of the five tasks were narrowly scoped, they were a real
grab-bag — research one of them turned into, a production deploy question on
another, a small feature here, a genuinely complex one there. A couple of
them touched things AI plainly didn’t have access to.</p>

<h2 id="where-it-kept-getting-stuck">Where it kept getting stuck</h2>

<p>Every session made real progress. It would work through as much as it could
figure out on its own — and it turns out that’s a lot — and then stop, not
because it was wrong, but because it didn’t have enough information to keep
going without me. It needed what I’d call a hard decision: something with
real tradeoffs, something that touched other people, something with no
obviously correct answer sitting in the codebase or the docs waiting to be
found.</p>

<p>So I’d stop, think it through, make the call, and hand it back. And almost
immediately the next session would need me for the same reason. Multiply
that by five or six running at once, and it stops feeling like supervising
AI and starts feeling like an all-day rotation of hard calls with no
breathing room in between.</p>

<h2 id="the-part-nobody-mentions">The part nobody mentions</h2>

<p>“Automate the boring stuff” is a fine mantra and I believe in it. I don’t
want to spend my time on something AI can handle competently, and increasingly
that’s most things. But that’s exactly the catch: if AI is taking every task
it can see end-to-end from the codebase and the docs, what’s left over is,
by definition, the stuff it <em>couldn’t</em> see end-to-end. The ambiguous calls.
The judgment calls. The ones with no clear winner.</p>

<p>Run five or six agents in parallel and you’re not doing a mix of easy and
hard work anymore. You’re doing hard problem, hard problem, hard problem,
one after another, with the easy layer stripped out from underneath you.</p>

<p>I moved a lot faster that day. I also finished it more drained than I have in
a long time. It’s not as simple as “AI makes everyone more productive.” It
makes the repetitive, boring parts of the job nearly free — genuinely great —
but it does that by concentrating everything hard onto the person left
holding the decisions. Do that without pacing yourself, and it’s a pretty
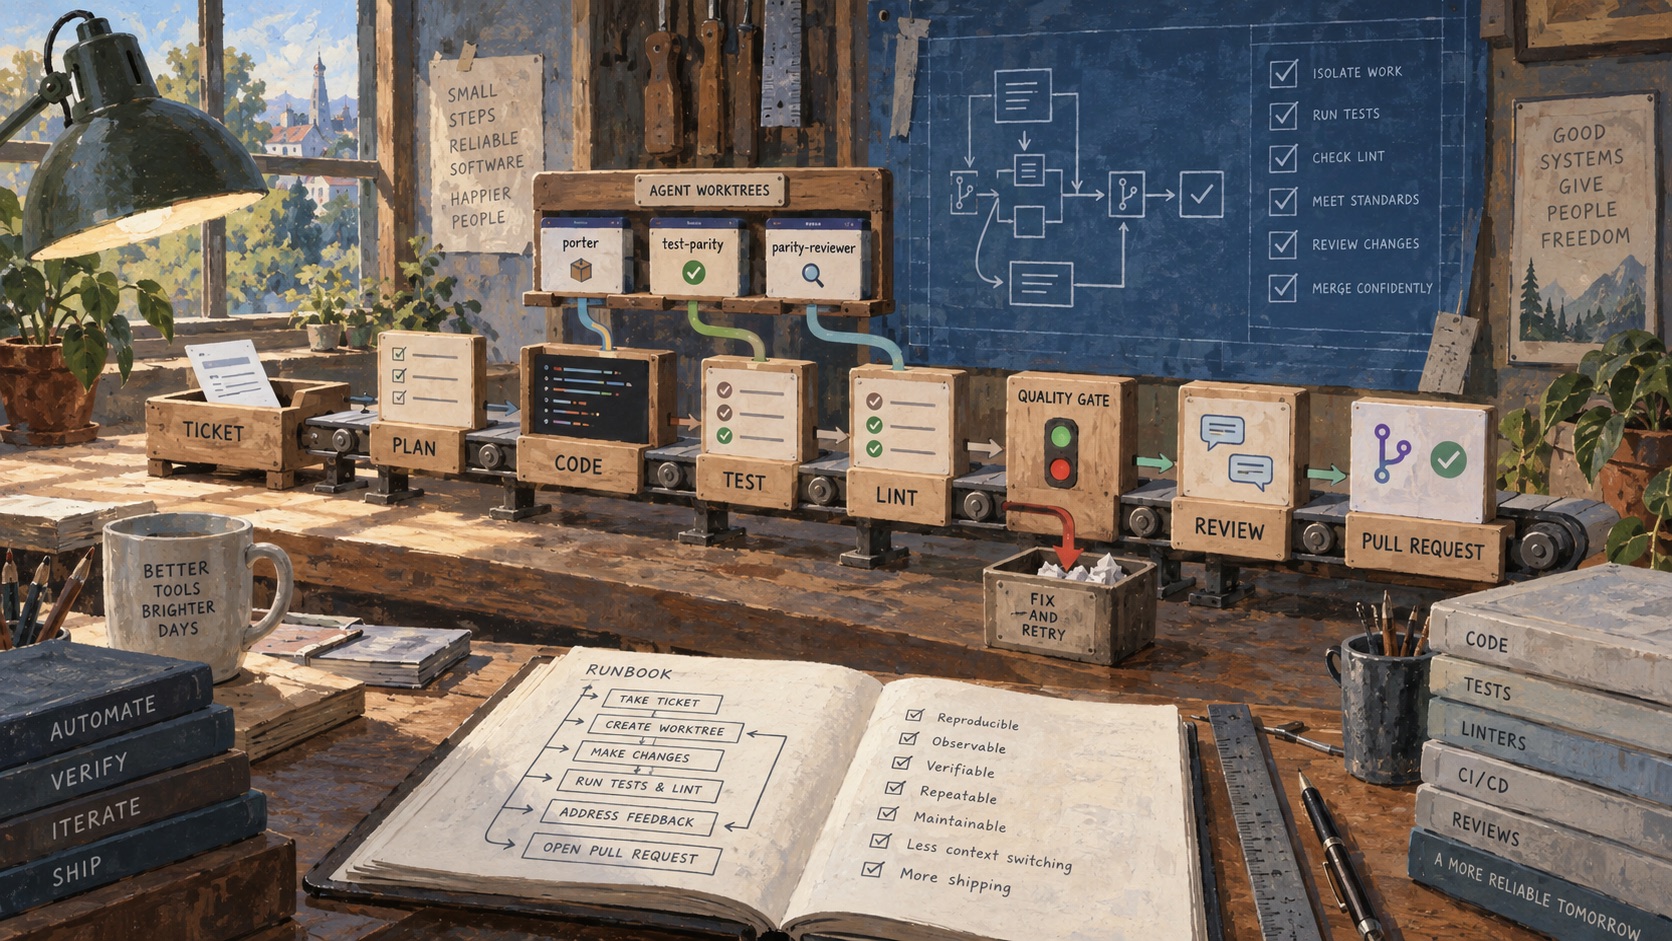
direct route to burnout.</p>]]></content><author><name>Jason Haas</name></author><category term="tools" /><summary type="html"><![CDATA[I let five AI sessions run in parallel with almost no upfront planning, just to see how far they'd get. They got further than I expected — and then stopped, one after another, on the exact same kind of problem: the one only I could decide.]]></summary></entry><entry><title type="html">Stop Prompting. Start Building a Runbook.</title><link href="https://signalandsawdust.com/stop-prompting-start-building-a-runbook" rel="alternate" type="text/html" title="Stop Prompting. Start Building a Runbook." /><published>2026-09-14T00:00:00+00:00</published><updated>2026-09-14T00:00:00+00:00</updated><id>https://signalandsawdust.com/stop-prompting-start-building-a-runbook</id><content type="html" xml:base="https://signalandsawdust.com/stop-prompting-start-building-a-runbook"><![CDATA[<p><img src="https://signalandsawdust.com/assets/runbook-not-prompting.jpg" alt="A painted illustration of a workshop desk with an open runbook and a
conveyor-belt pipeline of labeled stations — ticket, plan, code, test, lint,
quality gate, review, pull request — beside a rack of agent
worktrees" /></p>

<p>The interesting work was never the prompting. It’s building the scaffolding
that makes an agent’s output <em>verifiable</em> and its mistakes <em>cheap</em>. Everything
else below is downstream of that one idea.</p>

<h2 id="what-we-were-building">What we were building</h2>

<p>The service is a Go HTTP API — a build queue and dispatcher, a few hundred
files, on the order of 50,000 lines of code, more than half of that test
code. We were in the middle of absorbing a legacy TypeScript service into it:
porting endpoints over one at a time, with behavioral parity as the whole
game. Return a 500 where the old service returned a 409 and you’ve broken a
caller in production.</p>

<p>That combination — an existing service with strong conventions, a CI/CD setup
that already ran unit, integration, and end-to-end tests on every PR, and a
legacy implementation that doubled as a source of truth for correct behavior
— turned out to be close to the ideal shape of task for an agent. Low
ambiguity, high volume. Worth naming explicitly, because it’s not the same
claim as “agents solve greenfield design.” They don’t, or at least not this
kind of agent, not yet.</p>

<p>Measured against how this work went before:</p>

<table>
  <thead>
    <tr>
      <th>Work category</th>
      <th>Before</th>
      <th>With AI</th>
      <th>Impact</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Chore-sized tasks</td>
      <td>1–2 days</td>
      <td>~1 hour</td>
      <td>8–10x faster</td>
    </tr>
    <tr>
      <td>Complex tasks</td>
      <td>~1 week</td>
      <td>2–3 days</td>
      <td>2–3x faster</td>
    </tr>
    <tr>
      <td>Well-scoped projects</td>
      <td>baseline pace</td>
      <td>AI-assisted</td>
      <td>3–5x faster</td>
    </tr>
  </tbody>
</table>

<p>The gains showed up most on repetitive, decomposable, clearly scoped work —
which is a real result, but it’s also a specific one. It’s not “AI makes
everything faster,” it’s “AI changes the unit economics of a particular kind
of engineering work.”</p>

<h2 id="the-one-idea-underneath-everything">The one idea underneath everything</h2>

<p>Part of the team worked in VS Code with Copilot, I mostly worked in
OpenCode. Nobody wanted two sets of rules quietly drifting apart. So the
actual content — rules, scoped conventions, reusable commands, subagent
definitions — lived in one shared location, version controlled like any
other code, and each tool got a thin adapter that pointed at it.</p>

<table>
  <thead>
    <tr>
      <th>Artifact</th>
      <th>Source of truth</th>
      <th>OpenCode</th>
      <th>VS Code / Copilot</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Repo-wide rules</td>
      <td><code class="language-plaintext highlighter-rouge">AGENTS.md</code>, <code class="language-plaintext highlighter-rouge">.github/copilot-instructions.md</code></td>
      <td>read automatically</td>
      <td>read automatically</td>
    </tr>
    <tr>
      <td>Scoped conventions</td>
      <td><code class="language-plaintext highlighter-rouge">.github/instructions/*.instructions.md</code></td>
      <td>matched by an instructions glob</td>
      <td>matched by an <code class="language-plaintext highlighter-rouge">applyTo</code> glob</td>
    </tr>
    <tr>
      <td>Subagents</td>
      <td><code class="language-plaintext highlighter-rouge">.github/agents/*.agent.md</code></td>
      <td>referenced from <code class="language-plaintext highlighter-rouge">opencode.json</code></td>
      <td>read automatically</td>
    </tr>
    <tr>
      <td>Reusable commands</td>
      <td><code class="language-plaintext highlighter-rouge">.github/prompts/*.prompt.md</code></td>
      <td>a one-line stub in <code class="language-plaintext highlighter-rouge">.opencode/command/*.md</code></td>
      <td>read automatically as <code class="language-plaintext highlighter-rouge">/name</code></td>
    </tr>
    <tr>
      <td>MCP servers (issue tracker, wiki)</td>
      <td>—</td>
      <td><code class="language-plaintext highlighter-rouge">opencode.json</code></td>
      <td><code class="language-plaintext highlighter-rouge">.vscode/mcp.json</code></td>
    </tr>
  </tbody>
</table>

<p>The content itself lives under <code class="language-plaintext highlighter-rouge">.github/</code>, and each tool’s adapter is a few
lines at most. <code class="language-plaintext highlighter-rouge">.opencode/command/lint.md</code>, for example, is nothing but a
stub that captures its arguments and pulls in the real prompt from
<code class="language-plaintext highlighter-rouge">.github/prompts/lint.prompt.md</code> — Copilot reads that same shared file
natively as <code class="language-plaintext highlighter-rouge">/lint</code>. One playbook, two front doors.</p>

<h2 id="rules-written-as-scars-not-aspirations">Rules written as scars, not aspirations</h2>

<p>Every rules file I’ve seen looks like a wish list by default. Ours read more
like a runbook — the standard I held it to was: if you can’t name the
incident behind a rule, cut it.</p>

<p>A few examples, paraphrased: handlers decode, call the service layer, and
encode — no business logic in the handler. Use the shared test-database
harness for anything touching persistence, not a hand-rolled one per test
file. Don’t add error handling for conditions that can’t actually occur. Each
of those exists because something specific went wrong once, not because it
sounded like good practice in the abstract. And when a newer model shows up,
it’s worth going back and asking whether the rule is still earning its place
— some of it was scaffolding for a weaker model that a better one doesn’t
need anymore.</p>

<h2 id="commands-the-autonomy-dial-isnt-one-setting">Commands: the autonomy dial isn’t one setting</h2>

<p>The most useful command in the whole setup takes a ticket and walks it end to
end: read the ticket, cut a fresh worktree (never work in one that’s already
there, even if it looks clean), classify and route the work, get a
parity sign-off if it’s a port, then ship it — commit, push, open the PR,
comment the link back on the ticket. The line that actually makes it work is
the one telling it not to stop and ask permission between steps: read out
what’s coming, then keep going all the way to an opened PR, and only stop for
a genuine blocker.</p>

<blockquote>
  <p>You can always throw away a worktree. You can’t get back the twenty
minutes you spent typing “yes, continue.”</p>
</blockquote>

<p>Compare that to the linting command, which is almost the opposite
philosophy on purpose. Mechanical, reversible fixes — formatting, an
unchecked deferred <code class="language-plaintext highlighter-rouge">Close()</code>, an unused assignment — get auto-fixed.
Anything that needs judgment — a nil context where a real one was in scope,
a dead check, a coincidental type conversion — gets reported, not touched.
Never chase a green exit code for its own sake; if a “fix” would make the
code worse, don’t make it. The point isn’t that one command is more trusted
than the other. It’s that the autonomy dial should be set by how expensive
and how reversible a mistake would be, not by a blanket feeling about the
model.</p>

<h2 id="four-narrow-subagents-not-one-helpful-one">Four narrow subagents, not one helpful one</h2>

<p>Instead of one general assistant, the actual work was split across a small
number of narrowly scoped subagents:</p>

<table>
  <thead>
    <tr>
      <th>Subagent</th>
      <th>Job</th>
      <th>Write access</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>porter</td>
      <td>Port a single endpoint</td>
      <td>edit</td>
    </tr>
    <tr>
      <td>test-parity</td>
      <td>Write the parity tests for it</td>
      <td>edit</td>
    </tr>
    <tr>
      <td>parity-reviewer</td>
      <td>Read-only gate before a PR goes up</td>
      <td>none — diff/log/test/lint only</td>
    </tr>
    <tr>
      <td>spike-researcher</td>
      <td>Investigate, write up findings</td>
      <td>docs only</td>
    </tr>
  </tbody>
</table>

<p>None of them are allowed to assume a path. If a subagent can’t locate
something with a quick directory scan, it asks rather than guesses. Small
rule, but it eliminates a whole category of confidently-wrong behavior.</p>

<h2 id="the-verification-surface-is-the-whole-trick">The verification surface is the whole trick</h2>

<p>Nothing in this setup calls a raw test runner directly. Every check is a
named target that both your laptop and CI run identically:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>make lint        make test
make vuln        make cover
make integration-local
make api-smoke
</code></pre></div></div>

<p>The agent isn’t a special case that needs a separate trust model. It’s a
third user of an interface that already existed for humans. You’re not
asking “do I trust the model.” You’re asking “does it pass the gates” — the
same question you already ask of a human’s PR.</p>

<p>The strongest version of this: on every PR, CI also runs the <em>old</em> service’s
own end-to-end test suite against the <em>new</em> one. The thing being replaced
grades its replacement. That’s why the test-to-source ratio here is over
1:1 — the port is only worth doing if the safety net is denser than the code
it’s protecting.</p>

<h2 id="two-war-stories">Two war stories</h2>

<p><strong>The guardrail that did nothing.</strong> I tried to tidy up permission
configuration by moving it from one place into what looked like a cleaner,
more idiomatic location. Nicer diff. Except one of the two tools only parses
that configuration from a specific file format in a specific location — and
silently ignored the version I’d moved, running the “read-only” agent with
full default permissions instead. I only found out because I went and
actively probed it: gave the agent a task that should have been blocked and
watched it not get blocked.</p>

<blockquote>
  <p>A safety setting you’ve never tested is a safety setting you don’t
actually have.</p>
</blockquote>

<p><strong>The test that passed doing nothing.</strong> A test meant to verify every route
was documented in the API spec lived in the wrong package for months. It
still ran. It still passed. It just wasn’t testing anything, because it
was importing the wrong set of routes entirely. A green test that verifies
nothing is worse than no test, because it buys you confidence you didn’t
earn — and it’s the exact same failure mode as trusting a model’s output
because the output <em>looked</em> plausible. The signal looked right, so nobody
looked closer.</p>

<h2 id="running-several-agents-means-solving-a-concurrency-problem">Running several agents means solving a concurrency problem</h2>

<p>Once you’re cutting a fresh worktree per task, running several agents at once
is mechanically possible — until they collide on something shared. In our
case it was a local dev stack bound to fixed ports: two agents both trying to
run the full service locally at once was a bad afternoon. The fix was the
same fix you’d reach for with any shared mutable resource — eliminate it.
Default parallel work to unit and integration tests against an ephemeral,
per-run database instead of the shared stack. A few extra seconds of boot
time per run bought effectively unlimited concurrency.</p>

<p>The other resource that turned out to be scarce was context. A large design
document was getting pulled into every task’s context window whether or not
the task had anything to do with it. Worth a section of its own in the rules
file: lazy-load it, don’t preload it. Spend context on the task in front of
you, not on documents that merely might be relevant.</p>

<h2 id="five-things-worth-stealing">Five things worth stealing</h2>

<ol>
  <li>Put the actual content in one place and give each tool a thin adapter.
Don’t maintain two brains.</li>
  <li>Every verification step should be a named target that CI runs identically.
This is most of the trick.</li>
  <li>Write rules as scars, not aspirations. If you can’t name the incident, cut
the rule.</li>
  <li>Set the autonomy dial per task, not per tool — same repo, same model,
opposite settings depending on how expensive a mistake would be.</li>
  <li>Test your guardrails the same way you test your code. A restriction you’ve
never verified is not a restriction.</li>
</ol>]]></content><author><name>Jason Haas</name></author><category term="tools" /><summary type="html"><![CDATA[What it actually takes to get useful work out of coding agents in a 50k-line Go service — and why almost none of it turned out to be prompting.]]></summary></entry><entry><title type="html">2026: The Year the IDE Died</title><link href="https://signalandsawdust.com/2026-the-year-the-ide-died" rel="alternate" type="text/html" title="2026: The Year the IDE Died" /><published>2026-09-08T00:00:00+00:00</published><updated>2026-09-08T00:00:00+00:00</updated><id>https://signalandsawdust.com/2026-the-year-the-ide-died</id><content type="html" xml:base="https://signalandsawdust.com/2026-the-year-the-ide-died"><![CDATA[<p><img src="https://signalandsawdust.com/assets/ide-to-trash.jpg" alt="Pixel art: a hand flinging a VS Code window into a metal trash can beside a desk in a dim, blue-lit room" /></p>

<p>I’ve spent most of my career reaching for the lightest editor in the room —
notepad, vim, where the thing in front of you is the text and nothing else.
Sublime Text is old at this point, but it’s C++ under the hood and fast in a way
that still impresses me. And at the start of this year I was sitting in GoLand: a
JVM IDE with every battery included, the single heaviest tool I could have
picked.</p>

<p>I’ve barely opened it since spring. Not because I finally came around to my own
taste — because the agents got good enough that the question stopped mattering.</p>

<h2 id="ai-the-autocomplete-era-2023--2025">AI: The autocomplete era (2023 – 2025)</h2>

<p>Early GitHub Copilot autocomplete worked, in a narrow way. It was great for
boilerplate: function and class signatures, unit tests, anything repetitive. But
when I was trying to write something from scratch, it got in the way more than
it helped. I turned it off a lot.</p>

<p>Then I saw what Cursor was doing — generating code through chat, letting you
review the diff, iterating from there — and thought, <em>this is how it’s going to
be.</em> Chat existed elsewhere by then, but nobody had built the loop as well. Once
you get used to working that way, going back feels unbearably slow.</p>

<p>VS Code followed shortly behind, and on paper it was the obvious place for me to
land: quick enough, a mostly open-source core, good plugins, and it kept pace on
AI. JetBrains was in last place — powerful, batteries included, and slow and
cumbersome to sit in all day, a heavyweight JVM IDE that crashed constantly and
was consistently behind on the AI stuff. That’s where my frustration started.</p>

<p>Eventually VS Code caught up, with Copilot built right into it. As of this
writing I’d guess most engineers I know are working that way. It became my
default for a while too.</p>

<p>And yet the year opened with me back in GoLand, because its Go support is
genuinely excellent — deep built-ins, click-through navigation on anything.
Batteries included won out. It had Copilot bolted on, but the AI features always
trailed the frontier by a release or two. That was the trade I was still willing
to make in January.</p>

<h2 id="ai-the-small-chunks-era-january--march-2026">AI: The small-chunks era (January – March 2026)</h2>

<p>The workflow back then was chunking. “First let’s do the data model.” Review it.
“Now this route for the web API.” Run just those tests. Back and forth: <em>no, try
this approach, do this instead.</em> You had to keep the pieces small because you
had to review every one of them. That was the reality through the Opus 4.5 and
4.6 generation, and definitely with Sonnet — which is what I started on.</p>

<p>The IDE was genuinely useful for this. The code was right there next to the
chat.</p>

<h2 id="ai-the-full-throttle-era-spring-2026--now">AI: The full-throttle era (spring 2026 – now)</h2>

<p>But as the models got better — from around March, and especially over the
summer — I found I needed the editor less and less. I wasn’t editing code
anymore. I was reading diffs, occasionally clicking through to understand what
the agent had done.</p>

<p>The harness got slow. Running several things at once and keeping the context
straight was hard. At some point I realized the IDE wasn’t helping me, it was in
my way.</p>

<p>A coworker turned me on to an open-source tool called OpenCode. The appeal: it
runs any model — OpenAI, Anthropic, the Chinese models, and locally hosted ones.
And because it’s open source, you can edit the tool, harden it, and make it fit
whatever security requirements you’re working under. (Obviously you don’t send
anything to servers you don’t trust. It has to be a trusted environment.)</p>

<p>I started using it and liked it immediately — but I still wanted the IDE around,
to trick myself into believing I had some control over the code. That I was
still hand-chiseling some of it. I wasn’t. And I’d venture that most engineers
working near the frontier of this stuff aren’t either.</p>

<p>The real click came when I let go of the small pieces. The models — Opus 4.8
especially — got good enough that you can hand the agent a whole task, and if
you’ve set things up right, it just runs. It runs the tests. It checks CI. Once
that was true, the IDE had nothing left to do.</p>

<h2 id="long-live-the-terminal">Long live the terminal</h2>

<p>On top of that: I love the terminal. It’s just a great place to work. Unix-style
commands, vim, the OpenCode color scheme. I move extremely fast there. I can
spin up multiple git worktrees, let them run, and get pinged when something
needs input.</p>

<p>For review I use a diff viewer — GitHub Desktop is great for this, and OpenCode
has one built in too. If I don’t like something, I tell the agent, it tweaks it,
I look again.</p>

<p>Sometimes I’ll kick off the same problem three different ways in three different
worktrees, then pick the one I want or steer it further and throw the rest away.
Code is disposable now. It’s cheap. Don’t get attached to it.</p>

<p>The one thing I do miss is the debugger. GoLand — and VS Code to some extent —
have great debugging support and the ability to step through code, and for truly
complex codebases and situations that still has a place. But I’ve found AI to be
increasingly good at debugging, or at least at pointing a human in the right
direction.</p>

<p>So I’m ready to declare the integrated development environment officially dead.
I can live in the terminal. Vim is never going away. Long live the terminal,
long live vi.</p>]]></content><author><name>Jason Haas</name></author><category term="tools" /><summary type="html"><![CDATA[I started this year in GoLand and ended it in a terminal. Once the models got good enough to hand a whole task to, the IDE stopped earning its place on my screen. Here's how the workflow changed, and what I still miss.]]></summary></entry><entry><title type="html">How I’m Saving $15K on Our Kitchen Reno</title><link href="https://signalandsawdust.com/how-im-saving-15k-on-our-kitchen-reno" rel="alternate" type="text/html" title="How I’m Saving $15K on Our Kitchen Reno" /><published>2026-09-04T00:00:00+00:00</published><updated>2026-09-04T00:00:00+00:00</updated><id>https://signalandsawdust.com/how-im-saving-15k-on-our-kitchen-reno</id><content type="html" xml:base="https://signalandsawdust.com/how-im-saving-15k-on-our-kitchen-reno"><![CDATA[<p><img src="https://signalandsawdust.com/assets/kitchen-reno.jpg" alt="White oak kitchen cabinets with a light stone island, black pendant lights, and an espresso station" /></p>

<p>My wife and I are doing a kitchen renovation with a general contractor — new
countertops, new sinks, and a water line plumbed in for the fancy new espresso
machine. The last piece was the cabinets. Everything is stark white right now and
we’re just over it. We wanted to warm it up: white oak to replace the cabinet
doors, plus drawers in the lower bays so pots and pans are easier to grab.</p>

<p>Then we started getting quotes. Custom cabinet work came in at $10,000 and ran as
high as $20,000 depending on how custom we wanted to go.</p>

<p>That’s when my wife said: why don’t you just do it?</p>

<h3 id="some-background">Some background</h3>

<p>I’m a software engineer — an engineer at heart — who picked up woodworking as a
hobby during COVID and studied under the illustrious Steve Ramsey on YouTube. I
got really into it, learned the fundamentals, and have been steadily leveling up
ever since. There have been a lot of little projects along the way.</p>

<p>This is easily the biggest thing I’ve taken on. If you’ve done cabinets before,
you know there are a hundred small decisions to make, and the dimensions have to
be dead-on. We’re doing full overlay, so the reveals are tiny. Any imprecision
and things don’t fit.</p>

<h3 id="trying-claude-code-instead-of-sketchup">Trying Claude Code instead of SketchUp</h3>

<p>I’m proficient in SketchUp, and normally I’d draw the whole thing up there, model
it out from the front, and confirm everything fits before cutting anything.</p>

<p>I use AI constantly — Claude Code, Opus, the chat apps — for work and for random
personal stuff. For this project I’d been asking a lot of questions in the chat
UI. It holds context well, but I wanted more precision, a durable record of what
I’d decided, and everything in one place.</p>

<p>So I figured I’d use Claude Code:</p>

<ul>
  <li>specs and notes in markdown files</li>
  <li>a running log</li>
  <li>actual software that verifies the design and outputs cut lists and build steps</li>
</ul>

<p>I started the planning phase in Fable and described the problem without
specifying a language or framework — deliberately. I just said: you figure it
out.</p>

<p>What came back was a Python tool. (Python seems to be the default when you don’t
ask for anything else.) A TOML file holds all the dimensions and specs, Python
checks that everything fits, and the output is markdown — cut list and bill of
materials included.</p>

<h3 id="from-markdown-files-to-something-i-can-use-in-the-shop">From markdown files to something I can use in the shop</h3>

<p>Markdown worked well at first. I usually prefer plain text over anything else:
readable, easy to see what changed. But I kept wanting to check the cut list and
exact dimensions while I was standing in the shop, on my phone, without walking
back to the laptop.</p>

<p>So I told it: build me a web interface and publish it. It needs to be readable
and easy to navigate on a phone. And after every instruction, commit, push to
GitHub, and publish the update.</p>

<p>Here’s what that turned into:
<strong><a href="https://claude.ai/code/artifact/0a43f2da-8a57-4fdc-b51c-c45c4405f2a5">Kitchen Reno Shop Book</a></strong></p>

<p>I wasn’t reviewing code here. This isn’t production code, so I wasn’t
scrutinizing the implementation — I needed to quality-check the numbers, not the
internals. Git lets me roll back, and the artifact has its own version history.
So: just ship it. It stood up an artifact hosted on claude.ai, and I never had to
think about hosting at all.</p>

<p>The first pass was solid. A full cut list with plywood dimensions optimized to
minimize waste, plus some basic 3D drawings — just boxes, nothing crazy, but
useful.</p>

<h3 id="what-it-did-well">What it did well</h3>

<p>I could hand it the cabinet measurements, the door measurements, tell it I wanted
full overlay with 2-inch face frames, all the boring dimensions — then talk
through what I wanted, what wood, what sizes. It would scope the whole thing out
and immediately run the math: dimensions, cut list, the works.</p>

<p>For this specific kind of task it was excellent. Figuring out the optimal way to
cut sheets of plywood is exactly what AI should be doing. I used to use a
SketchUp plugin for that, and it worked fine, but this is so much easier.
Dimensional math, checking that things fit, running the verification code — great
at all of it.</p>

<p>Publishing to a site I can pull up on my phone is the other big win. I used to
just take notes in Apple Notes, which works, but having the numbers and the
images right there, always current, is a real upgrade. 10 out of 10.</p>

<h3 id="what-it-didnt-do-well">What it didn’t do well</h3>

<p>The frustration was spatial reasoning. When I asked about cut procedures or how
handles should be oriented, it got mixed up and didn’t really seem to know what
it was talking about. It has a decent grasp of woodworking, but nowhere near the
level it’s at with code. (This was mostly Opus 4.5 and 5, with the planning phase
in Fable.)</p>

<p>I went back and forth on this more times than I can count — QA it, tell it to fix
it, QA it again, tell it to fix it again. Sometimes it got hardware counts wrong.
I’d say I want 30 hinges, two or three per door, and it would do it and then
forget. Little things like that meant a lot of time spent checking output.</p>

<p>That was the bulk of my time on this project, honestly. Not QA’ing code — QA’ing
output.</p>

<h3 id="so-did-it-save-me-time">So did it save me time?</h3>

<p>The jury’s still out. It might have been faster to mock the whole thing up in
SketchUp, or even to work out of an Apple Note and a spreadsheet. (Excel can do
the math too, to be fair.)</p>

<p>But this was my first attempt at working this way. On the next project I’ll know
where the strengths and the weak spots are, and I expect it to go a lot faster.</p>]]></content><author><name>Jason Haas</name></author><category term="shop" /><summary type="html"><![CDATA[My wife and I are doing a kitchen renovation, and the cabinet quotes came back between $10,000 and $20,000. So I decided to build them myself — and I used Claude Code to plan the whole thing instead of SketchUp. Here's what worked and what didn't.]]></summary></entry><entry><title type="html">Making a simple link shortener with AWS and MySQL</title><link href="https://signalandsawdust.com/making-a-simple-link-shortener-with-aws-andmysql" rel="alternate" type="text/html" title="Making a simple link shortener with AWS and MySQL" /><published>2019-02-06T00:00:00+00:00</published><updated>2019-02-06T00:00:00+00:00</updated><id>https://signalandsawdust.com/making-a-simple-link-shortener-with-aws-andmysql</id><content type="html" xml:base="https://signalandsawdust.com/making-a-simple-link-shortener-with-aws-andmysql"><![CDATA[<p><img src="https://cdn-images-1.medium.com/max/1600/1*NaL3SxOBXbrwXrAciJyM3Q.jpeg" alt="" /></p>

<h3 id="making-a-simple-link-shortener-with-aws-and-mysql">Making a simple link shortener with AWS and MySQL</h3>

<p>Link shorteners are handy and pretty simple to implement. There are some free
services that you can use for this like bitly and google, but in some cases it
might be preferable to have the link shortener be under your own domain. Or
maybe you want to implement some additional analytics or features that the other
services don’t have. Let’s get started!</p>

<h3 id="usage">Usage</h3>

<p>The goal of this project is to create a service that turns any link into a short
link under you domain. For example:</p>

<p>POST <code class="language-plaintext highlighter-rouge">api.jasonrhaas.com</code></p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>{
  "url":  "reddit.com"
}
</code></pre></div></div>

<p>The response should be:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>{
  "tiny_url": "http://jasonrhaas.com/6vyv6"
}
</code></pre></div></div>

<p>When you go to that URL it should point you to reddit.com.</p>

<h3 id="architecture">Architecture</h3>

<p>When building something, I’m a big believer in using the right tool for the job.
In other words, I’m not going to use a batteries included web framework like
Django when all I need is a simple micro service. The tools I’m using for this
job are:</p>

<ul>
  <li>Flask</li>
  <li>MySQL</li>
  <li>Zappa (AWS Lamda + API Gateway)</li>
</ul>

<p>Zappa is a nice tool that makes it easy to deploy an event driven API. I find
the API Gateway user interface a bit cumbersome so its nice to have a framework
that allows me to do (almost) everything from my code editor and command line.</p>

<h3 id="implementation">Implementation</h3>

<p>To build this, I used a simple Flask application containing a single <code class="language-plaintext highlighter-rouge">Url</code>
SQLALchemy model and basically two functions, a <code class="language-plaintext highlighter-rouge">get_tiny_url</code> function and a
<code class="language-plaintext highlighter-rouge">get_long_url</code> function.</p>

<h4 id="model">Model</h4>

<p>The model looks like this:</p>

<script src="https://gist.github.com/jasonrhaas/320d9a4bd7a8233f3d1600f9e9c77920.js"> </script>

<p>If you aren’t familiar with model classes, I recommend checking out the <a href="http://flask-sqlalchemy.pocoo.org/2.3/quickstart/">Flask
SQLAlchemy Quickstart</a> for a
crash course. If you want to go a bit deeper into what database model classes
can provide, check out the <a href="https://docs.djangoproject.com/en/2.1/topics/db/models/">Django
Tutorial</a> on models.
The <a href="https://docs.sqlalchemy.org/en/latest/">SQLAlchemy documentation</a> is
comprehensive, but its very dense and technical and in my opinion is not a good
introduction to models.</p>

<p>In the <code class="language-plaintext highlighter-rouge">Url</code> model above, here are what the different tables are:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">id</code> — just a database id. In some cases (like for Django), this line isn’t even
necessary and is provided automatically.</li>
  <li><code class="language-plaintext highlighter-rouge">hash</code> — This is the what the long url gets turned into after it is shortened.</li>
  <li><code class="language-plaintext highlighter-rouge">long</code> — This is the original url.</li>
  <li><code class="language-plaintext highlighter-rouge">hits</code> — A simple numeric field that keeps track of how many times the link as
been accessed.</li>
</ul>

<p>We could expand this to provide even more information and analytics, like user
IP address, referring URL, timestamp of when it was accessed, etc. But for this
case I just needed something simple. The good part is this is easy to expand
upon later.</p>

<h4 id="get-tiny-url">Get Tiny URL</h4>

<p>The function to create the short link I decided to call <code class="language-plaintext highlighter-rouge">get_tiny_url</code>. The
function looks like this:</p>

<script src="https://gist.github.com/jasonrhaas/be559a46d24db938758dfa687945a09e.js"> </script>

<p>To explain this, I’m going to pick out a few lines.</p>

<h4 id="line-3">Line 3</h4>

<p>First we check to make sure that it is a POST request and a valid JSON object.
If it’s not, we simply redirect to the base url. This is kind of a “catch all”
approach and works fine for our use case, but it could be improved to have more
specific error catching and an appropriate error message for the user.</p>

<h4 id="line-9">Line 9</h4>

<p>It’s never* a good idea to store potentially sensitive information in a database
in clear text. As secure as your system is, there is always a chance that it may
be hacked and the data may be stolen. As a good rule of thumb, passwords should
<em>always</em> be hashed, for example.</p>

<p>In this case, I don’t have passwords, I’m just using the hash to identify a
unique URL. The area of password hashing is a complex and convoluted one. During
my research of implementing a JWT API Gateway Authorization solution, I found
that the Python <a href="https://docs.python.org/3/library/hashlib.html#blake2">Blake2</a>
library appears to be the new industry standard that is considered good enough
to hash passwords. In Python 3.6, this was added to the Python standard library.</p>

<p>When this line gets run, you end up with a hash like
<strong>53761004cf82ca63a62c430e8a409a6703d63f45</strong>. This hash is deterministic, but
its “one-way” meaning that it’s (almost) impossible derive the <code class="language-plaintext highlighter-rouge">long_url</code> from
this hash code on its own.</p>

<h4 id="line-12">Line 12</h4>

<p>This line is to try to find the url by the hash. This hash is unique per url, so
there should never be any duplicates in the database. If the <code class="language-plaintext highlighter-rouge">url</code> does not
exist, it will add it to the database.</p>

<h4 id="line-20">Line 20</h4>

<p>Finally, we make use of the
<a href="https://github.com/Alir3z4/python-short_url">short_url</a> Python library. This
library uses a bit-shuffling approach to deterministically generate URLs from a
number. In essence, this number corresponds to the database <code class="language-plaintext highlighter-rouge">id</code>. For our use
case, the number will point to an <code class="language-plaintext highlighter-rouge">id</code> in the database, which contains the
<code class="language-plaintext highlighter-rouge">long_url</code>.</p>

<h4 id="get-long-url">Get Long URL</h4>

<p>On to the reverse function, <code class="language-plaintext highlighter-rouge">get_long_url</code> which looks up the original URL given
the short link.</p>

<script src="https://gist.github.com/jasonrhaas/41ac789259c251133b98dab16558543a.js"> </script>

<p>Picking out a few lines of interest:</p>

<h4 id="line-5">Line 5</h4>

<p>This line takes the <code class="language-plaintext highlighter-rouge">/tiny_url</code> part of the link and translate it to the
<code class="language-plaintext highlighter-rouge">url_id</code> which matches up with the database <code class="language-plaintext highlighter-rouge">id</code>.</p>

<h4 id="line-13">Line 13</h4>

<p>This a simple counter keeping track of how many times the line gets access. This
information is then updated in the database.</p>

<h3 id="conclusion">Conclusion</h3>

<p>As you can see, coding up a link shortener is pretty straightforward! To test
this locally, all you need is a local MySQL database and Python3. In the next
blog post, I’ll talk in depth about how to set up your local environment and
also do automatically deployments using Continuous Integration and AWS.</p>]]></content><author><name>Jason Haas</name></author><category term="aws" /><summary type="html"><![CDATA[Link shorteners are handy and pretty simple to implement. There are some free services that you can use for this like bitly and google, but in some cases it might be preferable to have the link shortener be under your own domain.]]></summary></entry><entry><title type="html">Technology - The Final Frontier</title><link href="https://signalandsawdust.com/technology-the-final-frontier" rel="alternate" type="text/html" title="Technology - The Final Frontier" /><published>2017-11-17T00:00:00+00:00</published><updated>2017-11-17T00:00:00+00:00</updated><id>https://signalandsawdust.com/technology-the-final-frontier</id><content type="html" xml:base="https://signalandsawdust.com/technology-the-final-frontier"><![CDATA[<p><img src="https://cdn-images-1.medium.com/max/2000/1*OpY-PPIj2tPZ6Bc1DMiiIA.jpeg" alt="" />
<span class="figcaption_hack">Photo by SpaceX on Unsplash</span></p>

<p>Technology (and especially software) is constantly changing. Just because one
database, framework or programming language is popular now doesn’t mean it will
be in 5 years, or even 6 months. <strong>A career in technology is a career is
constant learning.</strong></p>

<p>So how do you keep up with the latest? Here are a few pointers from my own
experience:</p>

<h3 id="follow-hacker-news-newsycombinatorcom">Follow Hacker News (news.ycombinator.com)</h3>

<p>I’m not saying you need to be on top of this constantly. But this is the pulse
of the tech/startup world. Many experienced developers, tech CEOs, and
entrepreuers post and comment on here.</p>

<p>It’s important to see what stories are getting lots of comments, and get a feel
for the general setiment of the community. Also — new frameworks or technologies
are often posted here and talked about.</p>

<h3 id="follow-your-niche-field">Follow your niche field</h3>

<p>For me this is Python. I’m also interested in Entreprenuership. So I subscribe
to these two newsleters and at least browse through some of the content every
week:</p>

<p><a href="http://www.pythonweekly.com">www.pythonweekly.com</a><br />
<a href="http://www.foundersweekly.com">www.foundersweekly.com</a></p>

<p><strong>I know what you’re thinking: Email is the worst.</strong> And you would be correct in
thinking that. These newsletters are one of the far and few email subscriptions
that are actually meaningful and helpful. I recommend you find one similar in
your niche field.</p>

<h3 id="go-to-some-conferences">Go to (some) conferences</h3>

<p>Technology conferences are a dime a dozen these days. What technology are in you
into? Kubernetes perhaps? Mesos? Or maybe just all things Big Data? Or maybe you
are really into Blockchain. Regardless of what it is, there seems to be a
conference for everything.</p>

<p>Honestly I usually don’t learn a heck of a lot from the conferences, but they
are a good way to see what other people are thinking and where the industry is
going. <strong>It’s more of a “meet &amp; greet” and making sure I’m ahead of the curve
rather than anything else.</strong></p>

<p>Unfortunately, a lot of of them are charging in the realm of multiple hundreds
of dollars to attend. In my opinion, most of them aren’t worth paying  money for
(with the exception of PyCon, of course).</p>

<p>However, some conferences such as DeveloperWeek offer free tickets if you are a
developer. The idea is that the companies and recruiters pay the big fees for
the chance at recruiting talent (you!).** Look for these “developer deals”, and
take advantage of them.**</p>

<p>Also — if you work for a company that is hip enough to pay for your nerd
conference, definitely take advantage of that as well.</p>

<h3 id="speak-at-tech-meetups">Speak at Tech Meetups</h3>

<p>This is a good one. It will a give you a chance to give back to the community
and practice public speaking. Which — if you plan on running your own business
someday or even just being in a leadership position — is key.</p>

<p>Some Meetups, like the <em>Austin Python Meetup</em> have the regular talk, and then
“Lightning Talks” afterwards. A Lightning Talk just it’s typically 5–10 minutes
in length. <strong>Lightning Talks are a great way to get comfortable speaking in
front of the crowd.</strong></p>

<h3 id="use-open-source-and-contribute-to-it">Use Open Source, and Contribute to it</h3>

<blockquote>
  <p>Many people and organizations are relying on Open Source today, yet less than 1%
of users actually contribute back to Open Source.</p>
</blockquote>

<p>I totally made that quote up, but its probably pretty close. I know —
contributing to <em>Flask</em> can be intimidating. The regular contributors to popular
Open Source projects know their stuff. <strong>In fact — if companies see you are a
contributer to an Open Source Project, they may let you skip the demeaning “Live
Code Interview” process altogether.</strong></p>

<p>You don’t need to start with a big project, start small and work from there.
Also many projects have tags that specifically call out good tasks for people
new to the project — start with those.</p>

<h3 id="dont-fall-for-all-the-new-shiny-things">Don’t fall for all the new shiny things</h3>

<blockquote>
  <p>This world moves pretty fast. If you don’t stop and look around every once in a
while, you might miss it — Ferris Bueller</p>
</blockquote>

<p>Ok so there is always some new shiny thing that promises to be THE BEST DATABASE
EVER. You should definitely play around with all the new fancy things, but be
wary about using them in Production. Learn about it and figure out what it can
do that your existing stack or programming language can’t.</p>

<p><strong>You know what powers most of the forward thinking technology companies today?
Unix.</strong> Know when Unix was invented? The 70’s. Same goes with MySQL, Regular Old
Bash Scripts, and even (gasp) C++. Yea, C++ might not be “cool”, but there is a
reason why it still plays a big role in many of the tried and true tools that
are taken for granted today.</p>]]></content><author><name>Jason Haas</name></author><category term="career" /><summary type="html"><![CDATA[Technology (and especially software) is constantly changing. Just because one database, framework or programming language is popular now doesn’t mean it will be in 5 years, or even 6 months. A career in technology is a career is constant learning.]]></summary></entry><entry><title type="html">4 Keys to Fostering a Successful (Remote) Work Culture</title><link href="https://signalandsawdust.com/fostering-a-successful-remote-work-culture" rel="alternate" type="text/html" title="4 Keys to Fostering a Successful (Remote) Work Culture" /><published>2017-07-18T00:00:00+00:00</published><updated>2017-07-18T00:00:00+00:00</updated><id>https://signalandsawdust.com/fostering-a-successful-remote-work-culture</id><content type="html" xml:base="https://signalandsawdust.com/fostering-a-successful-remote-work-culture"><![CDATA[<p>Teams working remotely is more common then ever.  The combination of flexibility, high speed Internet, and the right tools make working remotely a viable option for may teams.  It has given rise to a whole generation of people that not only <em>can</em> work remotely, they <a href="http://www.alliedtelecom.net/why-embracing-remote-work-tech-helps-attract-retain-millennial-employees/"><em>expect</em> it</a>.</p>

<p>What do I know about working remotely?  I’ve worked successfully in a remote capacity for almost 3 years.  In that time, I traveled around the world with a program called Remote Year while working remotely.  <strong>I am passionate about fostering a culture that allows remote teams not only work together, but thrive.</strong></p>

<p>Here are the 4 traits that are absolutely essential to fostering a healthy (remote) work culture.</p>

<h2 id="1-open-communication">1. Open communication</h2>

<p><strong>By far the most important part of a successful remote work culture is open communication</strong>. What do I mean by this?  Think about how a traditional office operates.  There are conversations that happen in the hallway, at the water cooler, in meetings, in the cafeteria.  Sometimes the conversation is casual but other times its important work stuff that should be shared with your co-workers.</p>

<p>I can’t tell you how many times in the past I’ve made some big technical decisions by bumping into a senior engineer in the hallway and asking his advice.  Sometimes bouncing ideas off other people helps you solve a problem.</p>

<p>In fact, this is the #1 reason companies like to co-locate and put everyone in a single space.  This is good for fostering ideas and innovation, but very bad for solving hard problems that require <a href="http://calnewport.com/books/deep-work/">Deep Work</a>.</p>

<p>Making important decisions without review among your peers is often a bad idea.  Ideally the whole core engineering staff would also be involved at some level to validate ideas.  In a traditional office, this usually means meetings.  However, it’s pretty well understood that meetings are a <a href="https://www.themuse.com/advice/how-much-time-do-we-spend-in-meetings-hint-its-scary">colossal waste of time and resources</a>.</p>

<p><strong>The solution in a remote work environment is open communication using asynchronous tools</strong>.  For software development, this often includes tools such as:</p>

<ul>
  <li>Slack (asynchronous chat)</li>
  <li>Github (asynchronous software review)</li>
  <li>JIRA (asynchronous planning)</li>
  <li>Google Hangouts (synchronous meetings)</li>
</ul>

<p>You can swap any of these out for your tool set of choice.  By far the most import part of this whole section is this:</p>

<h3 id="using-public-forums-and-for-most-conversations">Using public forums and for most conversations</h3>

<p>I’ll stress this again, have conversations in a public place!  Avoid direct messages like the plague.  DM’s should not be used unless absolutely necessary, and the information needs to be private with that individual.</p>

<p>When a new employee comes on board, it can be tempting to use DM’s because he or she might be intimidated by asking “stupid questions” in a public forum.  But, it needs to be stressed to them that having discussions in public is essential.</p>

<p>There are several advantages of using public channels vs. private channels or direct messages:</p>

<h3 id="avoiding-redundancy">Avoiding redundancy</h3>

<p>There is nothing more annoying or inefficient than repeating the same question or relaying the exact information to 3, 4, 5, or 50 people over and over again.  Why not just say it once in a public channel?</p>

<h3 id="open-accountability">Open accountability</h3>

<p>Is the boss wondering what you are working on or why a project is taking so long?  Instead of harassing you on a regular interval, all they have to do is catch up on the public channels.  At that point they can see what is going and if they want to step in to help.</p>

<h3 id="knowledge-sharing">Knowledge sharing</h3>

<p>I once worked with a senior engineer that refused to share any of his knowledge with anyone.  Something broken?  He’ll fix it for you, but won’t tell you how he did.  This is a horrible engineering culture, and its actually really bad for the company.  What if he leaves the company?  It puts the company is a bad position.</p>

<p><strong>People like to learn new things.  Found out a better way to deploy your code?  Share it with the team.</strong></p>

<h2 id="2--accountability">2.  Accountability</h2>

<p>Something that holds bigger or more traditional companies back from allowing their employees to work part or full time remote is accountability.  The belief goes that if employees are being “watched” in the office they will slack off.</p>

<p>The truth is, if you have hired the right people, the opposite will be true.  <strong>In fact, there are a lot of studies that show that people are actually more productive when they are free from the distractions of the office.</strong></p>

<p>So how do you stay accountable as an employee?  Here are some ideas to build an accountable culture.</p>

<ul>
  <li><strong>Daily standups</strong>.  A 15 minute synchronous meeting serves as face time for the team to talk about what they are working on today and if there are any blockers.  You can also have a #daily-standup channel to provide more detail on Slack.</li>
  <li><strong>Daily announcements</strong>.  This channel is to let people know when you aren’t working.  Have to run some errands or want to do some laundry?  No problem, let the team know in this channel, and when you are back working let them know again.  No need to bother people, but if they want to know where you are, it should be in this channel.</li>
  <li><strong>Task tracking</strong>.  I won’t get into the whole Agile methodology here, but I want to emphasize that your team should break tasks out into small, manageable chunks.  This should improve velocity and allow for quick wins.  Also, surveys show that engineers are happier when they are <a href="https://insights.stackoverflow.com/survey/2017#work-how-are-job-satisfaction-and-committing-code-related">deploying code often</a>. <strong>As a general rule of thumb, try to make tasks that take no longer than 3 days to complete.</strong></li>
  <li><strong>Schedule push</strong>. If something is going to take longer than expected, report this early on.  Make it known in a public slack channel so there are no surprises and get someone to help.</li>
</ul>

<h2 id="3--batching-tasks">3.  Batching Tasks</h2>

<p>Schedule meetings in chunks to allow for proper Deep Work time.  Ever wonder why Hackathons exist?  <strong>Its because of the simple fact that people are more productive with uninterrupted time to focus on <a href="http://calnewport.com/books/deep-work/">their work</a>.</strong> .</p>

<p>There is a great article I read I while back that talks about the two types of people in a company:  <a href="http://www.paulgraham.com/makersschedule.html">the managers and the makers</a>.  The Managers have their whole day booked up, meeting after meeting, jumping from one thing to the next.  Their work often requires scheduling, high level oversight, meeting with clients or other managers.  If the work they are doing doesn’t require Deep Work, this is a fine thing.</p>

<p>The Makers on the other hand require time for Deep Work to truly be productive.  <strong>Jumping from one task to the next is counter productive as an engineer.</strong>  This is part of the reason why many software developers report doing their best work late at night.  The Managers should keep this in mind and try to batch weekly meetings all on one day, and keep other meetings during the week to a specific chunk of time, such as 9 - 12am, and leave the afternoon for engineering work.</p>

<p>In my last job, I often railed back at the constant stream of meetings.  I like to use the analogy of comparing software development to driving a manual transmission car.</p>

<p><strong>My best work is done when I’m in 6th gear</strong>.  But to get to 6th gear I have to go through all of the gears:  1st, 2nd, 3rd, 4th, 5th, and then 6th.  When I’m in 6th gear I am “in the zone” or “in flow”.  If I get interrupted while I’m in any of the gears and have to switch tasks, I have to restart in 1st gear and work my way up again, similar to having to stop a car at a stop sign.</p>

<h2 id="4--innovative-and-open-culture">4.  Innovative and Open Culture</h2>

<p>The best ideas can come from anywhere.  They can come from the CEO, or from the Jr. Engineer that was just hired.  Different people in the company have different perspectives on how things work, and may have an idea to improve or help grow the company.  It’s important to encourage an environment of innovation, and one that allows everyone to put their ideas in a public space, without fear.  Even if the idea will never be implemented, its important to hear ideas from all sides.</p>

<p>Some of my best work has come from this kind of innovative culture.  Most companies have some sort of road map that is broken up into tasks, with some schedule on how to get there.  <strong>The thing is, once engineering starts gaining a deeper understanding of how to solve the problem, there may be alternative approaches that drastically improve the product.</strong>  This applies particularly in the technology industry which is changing constantly.</p>

<p>I remember when I first discovered Kibana for Elastic Search.  At the time the company had a lot of data that was sitting around in raw files, S3, or a SQL database.  While doing some data analysis for the CEO, I stumbled upon the out-of-the-box visualization capabilities of <a href="https://www.elastic.co/products/kibana">Kibana</a>.  I read up on it, started indexing the data to Elastic Search, and created some basic visualizations with Kibana.</p>

<p>When I first told my boss about this, he was frustrated that I wasn’t working on my assigned tasks and that I was “wasting” my time playing with this new technology.  However, as soon as I demonstrated this to my boss and relevant stakeholders they were blown away with the capabilities.  This side project alone opened up an entire new capability to the company and our customers, and helped to propel the company’s technology in to the future.</p>

<h2 id="call-to-action">Call to Action</h2>

<p>If you work in a remote culture, or even an office culture, pick one of these traits and see how your company culture stacks up.  If the company is lacking in one of these areas, lead by example.  Start sharing things in public, share your ideas, and encourage others to do the same.  Another idea is to get the buy in of the leadership team, point them to this article and convince them to give it a try for a quarter.</p>]]></content><author><name>Jason Haas</name></author><category term="remote" /><summary type="html"><![CDATA[Teams working remotely is more common then ever. The combination of flexibility, high speed Internet, and the right tools make working remotely a viable option for may teams. It has given rise to a whole generation of people that not only can work remotely, they expect it.]]></summary></entry><entry><title type="html">Adding a simple API to your Postgres database</title><link href="https://signalandsawdust.com/adding-a-simple-api-to-your-postgres-database" rel="alternate" type="text/html" title="Adding a simple API to your Postgres database" /><published>2017-07-17T00:00:00+00:00</published><updated>2017-07-17T00:00:00+00:00</updated><id>https://signalandsawdust.com/adding-a-simple-api-to-your-postgres-database</id><content type="html" xml:base="https://signalandsawdust.com/adding-a-simple-api-to-your-postgres-database"><![CDATA[<p>When designing systems or platforms, it is very common to use a relational database such as MySQL or Postgres as a backend data storage.  In order to access this data from a remote endpoint, it’s very handy to have an API that can serve out proper JSON data.</p>

<p>In this  post I’m going to discuss one way to approach this problem.  I’m a huge fan of simple, elegant approaches, and I think this fits the bill nicely.</p>

<p>I will be using some code that I wrote for the <a href="https://codefordc.org">CodeForDC</a> housing insights project.</p>

<h2 id="the-state-of-things">The state of things</h2>

<p>I volunteer some of my time to the <a href="https://github.com/codefordc/housing-insights">Housing-Insights</a> project to help out with the backend and API design and implementation.  The current backend design at a high level consists of:</p>

<ul>
  <li>Download open data</li>
  <li>Parse and clean data</li>
  <li>Add tables to Postgres database</li>
  <li>Access data via custom Flask API endpoints</li>
</ul>

<p>Flask is a great Python framework for making dead simple APIs.  It is my go to if I need a lightweight application to serve up some data.  The syntax is as simple as this:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="kn">from</span> <span class="nn">flask</span> <span class="kn">import</span> <span class="n">Flask</span>
<span class="n">app</span> <span class="o">=</span> <span class="n">Flask</span><span class="p">(</span><span class="n">__name__</span><span class="p">)</span>

<span class="o">@</span><span class="n">app</span><span class="p">.</span><span class="n">route</span><span class="p">(</span><span class="s">"/"</span><span class="p">)</span>
<span class="k">def</span> <span class="nf">hello</span><span class="p">():</span>
    <span class="k">return</span> <span class="s">"Hello World!"</span></code></pre></figure>

<p>That is all the code you need to get a simple endpoint up and running.  If you want to create some API endpoints on your database, a simple approach is to use the Postgres <code class="language-plaintext highlighter-rouge">psycopg2</code> module for Python and run SQL queries as needed, then return the results.</p>

<p>And indeed, this works out pretty well.  To get raw data from tables, you can do something like this:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="o">@</span><span class="n">application</span><span class="p">.</span><span class="n">route</span><span class="p">(</span><span class="s">'/api/raw/&lt;table&gt;'</span><span class="p">,</span> <span class="n">methods</span><span class="o">=</span><span class="p">[</span><span class="s">'GET'</span><span class="p">])</span>
<span class="o">@</span><span class="n">cross_origin</span><span class="p">()</span>
<span class="k">def</span> <span class="nf">list_all</span><span class="p">(</span><span class="n">table</span><span class="p">):</span>
    <span class="s">""" Generate endpoint to list all data in the tables. """</span>

    <span class="n">application</span><span class="p">.</span><span class="n">logger</span><span class="p">.</span><span class="n">debug</span><span class="p">(</span><span class="s">'Table selected: {}'</span><span class="p">.</span><span class="nb">format</span><span class="p">(</span><span class="n">table</span><span class="p">))</span>
    <span class="k">if</span> <span class="n">table</span> <span class="ow">not</span> <span class="ow">in</span> <span class="n">tables</span><span class="p">:</span>
        <span class="n">application</span><span class="p">.</span><span class="n">logger</span><span class="p">.</span><span class="n">error</span><span class="p">(</span><span class="s">'Error:  Table does not exist.'</span><span class="p">)</span>
        <span class="n">abort</span><span class="p">(</span><span class="mi">404</span><span class="p">)</span>

    <span class="n">conn</span> <span class="o">=</span> <span class="n">engine</span><span class="p">.</span><span class="n">connect</span><span class="p">()</span>
    <span class="n">q</span> <span class="o">=</span> <span class="s">'SELECT row_to_json({}) from {} limit 1000;'</span><span class="p">.</span><span class="nb">format</span><span class="p">(</span><span class="n">table</span><span class="p">,</span> <span class="n">table</span><span class="p">)</span>
    <span class="n">proxy</span> <span class="o">=</span> <span class="n">conn</span><span class="p">.</span><span class="n">execute</span><span class="p">(</span><span class="n">q</span><span class="p">)</span>
    <span class="n">results</span> <span class="o">=</span> <span class="p">[</span><span class="n">x</span><span class="p">[</span><span class="mi">0</span><span class="p">]</span> <span class="k">for</span> <span class="n">x</span> <span class="ow">in</span> <span class="n">proxy</span><span class="p">.</span><span class="n">fetchmany</span><span class="p">(</span><span class="mi">1000</span><span class="p">)]</span> <span class="c1"># Only fetching 1000 for now, need to implement scrolling
</span>    <span class="n">conn</span><span class="p">.</span><span class="n">close</span><span class="p">()</span>

    <span class="k">return</span> <span class="n">jsonify</span><span class="p">(</span><span class="n">items</span><span class="o">=</span><span class="n">results</span><span class="p">)</span></code></pre></figure>

<p>Using the simple SQL statement</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>'SELECT row_to_json({}) from {} limit 1000;'.format(table, table)`
</code></pre></div></div>

<p>it will return 1000 rows from whatever table you select in the <code class="language-plaintext highlighter-rouge">table</code> variable.  This value comes from the Flask route <code class="language-plaintext highlighter-rouge">'/api/raw/&lt;table&gt;', methods=['GET']</code>.</p>

<p>But, as Raymond Hettinger likes to say…</p>

<blockquote>
  <p>there must be a better way</p>
</blockquote>

<p>And there is.</p>

<h2 id="flask-restless"><a href="https://flask-restless.readthedocs.io">Flask Restless</a></h2>

<p>Flask-Restless is a plugin for Flask that takes advantage of SQL Alchemy’s Object Relational Mappers to generate quick and easy endpoints.  If you have defined your database schema using SQLA (recommended), there is quite a bit of functionality out of the box.  Some examples:</p>

<ul>
  <li>Endpoints can be generated from any model</li>
  <li>Auto pagination</li>
  <li>JSON based search</li>
  <li>Pre-processors and post-processors</li>
</ul>

<p>So thats a great way to start off accessing the database, and the pagination feature makes sure you don’t end up pulling too much data at once.</p>

<p>But, here is the problem:  the database schema was not defined in SQLA.  Sigh.  But, there is a solution to that as well.</p>

<h2 id="sql-alchemy-automap"><a href="http://docs.sqlalchemy.org/en/latest/orm/extensions/automap.html">SQL Alchemy Automap</a></h2>

<p>SQLA includes a feature called <code class="language-plaintext highlighter-rouge">automap</code> that is able to “reflect” information about your database tables and automatically generate the models.  Using this approach, you can now take advantage of the features that SQLA and Flask Restless have to offer.</p>

<p>The code is pretty simple:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="n">application</span> <span class="o">=</span> <span class="n">Flask</span><span class="p">(</span><span class="n">__name__</span><span class="p">)</span>
<span class="n">application</span><span class="p">.</span><span class="n">config</span><span class="p">[</span><span class="s">'SQLALCHEMY_DATABASE_URI'</span><span class="p">]</span> <span class="o">=</span> <span class="n">connect_str</span>
<span class="n">application</span><span class="p">.</span><span class="n">config</span><span class="p">[</span><span class="s">'SQLALCHEMY_TRACK_MODIFICATIONS'</span><span class="p">]</span> <span class="o">=</span> <span class="bp">False</span>

<span class="n">db</span> <span class="o">=</span> <span class="n">SQLAlchemy</span><span class="p">(</span><span class="n">application</span><span class="p">)</span>
<span class="n">Base</span> <span class="o">=</span> <span class="n">automap_base</span><span class="p">()</span>

<span class="n">metadata</span> <span class="o">=</span> <span class="n">MetaData</span><span class="p">(</span><span class="n">bind</span><span class="o">=</span><span class="n">db</span><span class="p">)</span>

<span class="n">Base</span><span class="p">.</span><span class="n">prepare</span><span class="p">(</span><span class="n">db</span><span class="p">.</span><span class="n">engine</span><span class="p">,</span> <span class="n">reflect</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>

<span class="n">db</span><span class="p">.</span><span class="n">session</span><span class="p">.</span><span class="n">commit</span><span class="p">()</span>

<span class="n">BuildingPermits</span> <span class="o">=</span> <span class="n">Base</span><span class="p">.</span><span class="n">classes</span><span class="p">.</span><span class="n">building_permits</span>
<span class="n">Census</span> <span class="o">=</span> <span class="n">Base</span><span class="p">.</span><span class="n">classes</span><span class="p">.</span><span class="n">census</span>
<span class="n">CensusMarginOfError</span> <span class="o">=</span> <span class="n">Base</span><span class="p">.</span><span class="n">classes</span><span class="p">.</span><span class="n">census_margin_of_error</span>
<span class="n">Crime</span> <span class="o">=</span> <span class="n">Base</span><span class="p">.</span><span class="n">classes</span><span class="p">.</span><span class="n">crime</span>
<span class="n">DcTax</span> <span class="o">=</span> <span class="n">Base</span><span class="p">.</span><span class="n">classes</span><span class="p">.</span><span class="n">dc_tax</span>
<span class="n">Project</span> <span class="o">=</span> <span class="n">Base</span><span class="p">.</span><span class="n">classes</span><span class="p">.</span><span class="n">project</span>
<span class="n">ReacScore</span> <span class="o">=</span> <span class="n">Base</span><span class="p">.</span><span class="n">classes</span><span class="p">.</span><span class="n">reac_score</span>
<span class="n">RealProperty</span> <span class="o">=</span> <span class="n">Base</span><span class="p">.</span><span class="n">classes</span><span class="p">.</span><span class="n">real_property</span>
<span class="n">Subsidy</span> <span class="o">=</span> <span class="n">Base</span><span class="p">.</span><span class="n">classes</span><span class="p">.</span><span class="n">subsidy</span>
<span class="n">Topa</span> <span class="o">=</span> <span class="n">Base</span><span class="p">.</span><span class="n">classes</span><span class="p">.</span><span class="n">topa</span>
<span class="n">WmataDist</span> <span class="o">=</span> <span class="n">Base</span><span class="p">.</span><span class="n">classes</span><span class="p">.</span><span class="n">wmata_dist</span>
<span class="n">WmataInfo</span> <span class="o">=</span> <span class="n">Base</span><span class="p">.</span><span class="n">classes</span><span class="p">.</span><span class="n">wmata_info</span>

<span class="n">models</span> <span class="o">=</span> <span class="p">[</span><span class="n">BuildingPermits</span><span class="p">,</span> <span class="n">Census</span><span class="p">,</span> <span class="n">CensusMarginOfError</span><span class="p">,</span> <span class="n">Crime</span><span class="p">,</span> <span class="n">DcTax</span><span class="p">,</span> <span class="n">Project</span><span class="p">,</span> <span class="n">ReacScore</span><span class="p">,</span>
          <span class="n">RealProperty</span><span class="p">,</span> <span class="n">Subsidy</span><span class="p">,</span> <span class="n">Topa</span><span class="p">,</span> <span class="n">WmataDist</span><span class="p">,</span> <span class="n">WmataInfo</span>
          <span class="p">]</span>

<span class="n">db</span><span class="p">.</span><span class="n">init_app</span><span class="p">(</span><span class="n">application</span><span class="p">)</span>

<span class="n">manager</span> <span class="o">=</span> <span class="n">APIManager</span><span class="p">(</span><span class="n">application</span><span class="p">,</span> <span class="n">flask_sqlalchemy_db</span><span class="o">=</span><span class="n">db</span><span class="p">)</span>

<span class="k">for</span> <span class="n">model</span> <span class="ow">in</span> <span class="n">models</span><span class="p">:</span>
    <span class="c1"># https://github.com/jfinkels/flask-restless/pull/436
</span>    <span class="n">model</span><span class="p">.</span><span class="n">__tablename__</span> <span class="o">=</span> <span class="n">model</span><span class="p">.</span><span class="n">__table__</span><span class="p">.</span><span class="n">name</span>
    <span class="n">manager</span><span class="p">.</span><span class="n">create_api</span><span class="p">(</span><span class="n">model</span><span class="p">,</span> <span class="n">methods</span><span class="o">=</span><span class="p">[</span><span class="s">'GET'</span><span class="p">])</span>


<span class="o">@</span><span class="n">application</span><span class="p">.</span><span class="n">route</span><span class="p">(</span><span class="s">'/'</span><span class="p">)</span>
<span class="k">def</span> <span class="nf">hello</span><span class="p">():</span>
    <span class="k">return</span><span class="p">(</span><span class="s">"The Housing Insights API Rules!"</span><span class="p">)</span>


<span class="k">if</span> <span class="n">__name__</span> <span class="o">==</span> <span class="s">'__main__'</span><span class="p">:</span>
    <span class="n">application</span><span class="p">.</span><span class="n">run</span><span class="p">(</span><span class="n">host</span><span class="o">=</span><span class="s">'0.0.0.0'</span><span class="p">,</span> <span class="n">port</span><span class="o">=</span><span class="mi">5000</span><span class="p">)</span></code></pre></figure>

<p>That chunk of code above is all the code you need to reflect your current tables into the SQLA model and serve up the API using Flask Restless.  Pretty badass if you ask me.  I’ll walk through it a little bit to describe what is going on.</p>

<p><code class="language-plaintext highlighter-rouge">db = SQLAlchemy(application)</code></p>

<p>is Flask Restless wrapper around the basic SQLA engine creator.  You pass it your Flask application object.</p>

<p><code class="language-plaintext highlighter-rouge">Base.prepare(db.engine, reflect=True)</code></p>

<p>here is where you tell SQLA automap which database to use, and that you want it to reflect your current database tables.</p>

<p><code class="language-plaintext highlighter-rouge">BuildingPermits = Base.classes.building_permits</code></p>

<p>here is where you pull the auto generated model out of <code class="language-plaintext highlighter-rouge">Base.classes</code> and assign it a model name.</p>

<p><code class="language-plaintext highlighter-rouge">manager = APIManager(application, flask_sqlalchemy_db=db)</code></p>

<p>create a APIManager Flask Restless API.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>for model in models:
    # https://github.com/jfinkels/flask-restless/pull/436
    model.__tablename__ = model.__table__.name
    manager.create_api(model, methods=['GET'])
</code></pre></div></div>

<p>For this chunk of code, we are creating a basic GET endpoint for all of the models defined above.  The line above it <code class="language-plaintext highlighter-rouge">model.__tablename__</code> is a workaround for an issue that will be fixed in version 1.0 of the code.</p>

<h2 id="conclusion">Conclusion</h2>

<p>If you need a quick and dirty API on top of your SQL database, look no further than Flask and Flask Restless.  It’s a great way to get started.  However, you still may have to define some custom endpoints, since Flask Restless doesn’t do everything.  However using the ORM approach to create your endpoints probably leads to more maintainable and more clearly written code.</p>

<p><strong>My question to the devs out there is this</strong>:  How does this approach compare to the Django ORM?  I know Django has a lot of capability right out of the box, and has its own built in ORM, and Rest API plugin.  I’m curious to compare it to the Flask/SQLA approach in terms of ease of use, flexibility, and overall capability.</p>]]></content><author><name>Jason Haas</name></author><category term="python" /><summary type="html"><![CDATA[When designing systems or platforms, it is very common to use a relational database such as MySQL or Postgres as a backend data storage. In order to access this data from a remote endpoint, it’s very handy to have an API that can serve out proper JSON data.]]></summary></entry></feed>